fig3
From: Assistive assessment of neurological dysfunction via eye movement patterns and ocular biometrics
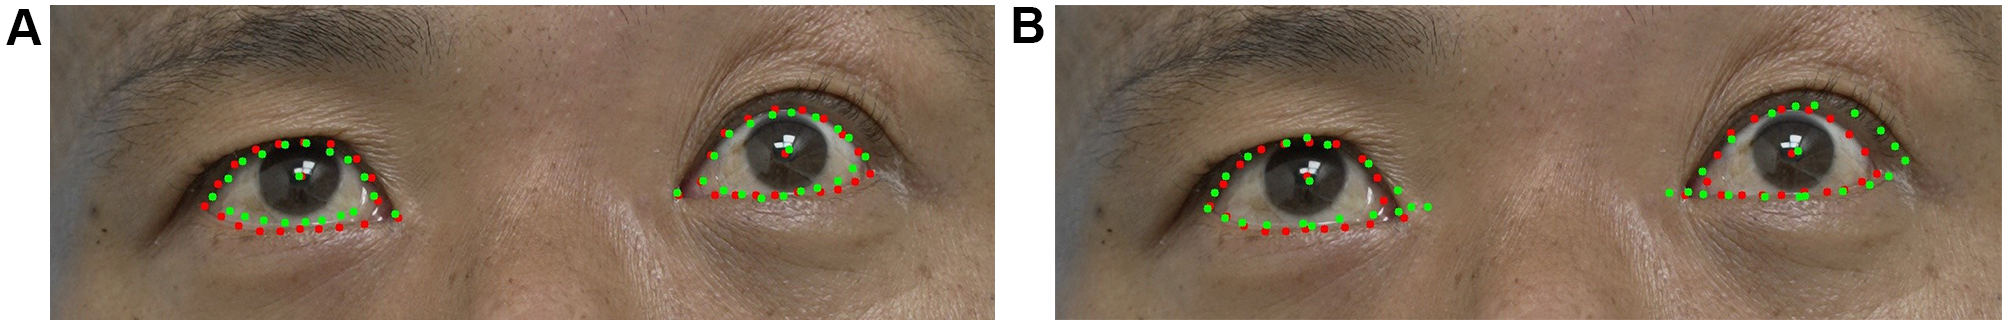
Figure 3. Error comparison for 40-point eye landmarks detection. Red points indicate the ground truth (manual annotation), while green points represent the model’s predictions. (A) OFKNet; (B) MediaPipe Face Landmarker.