fig5
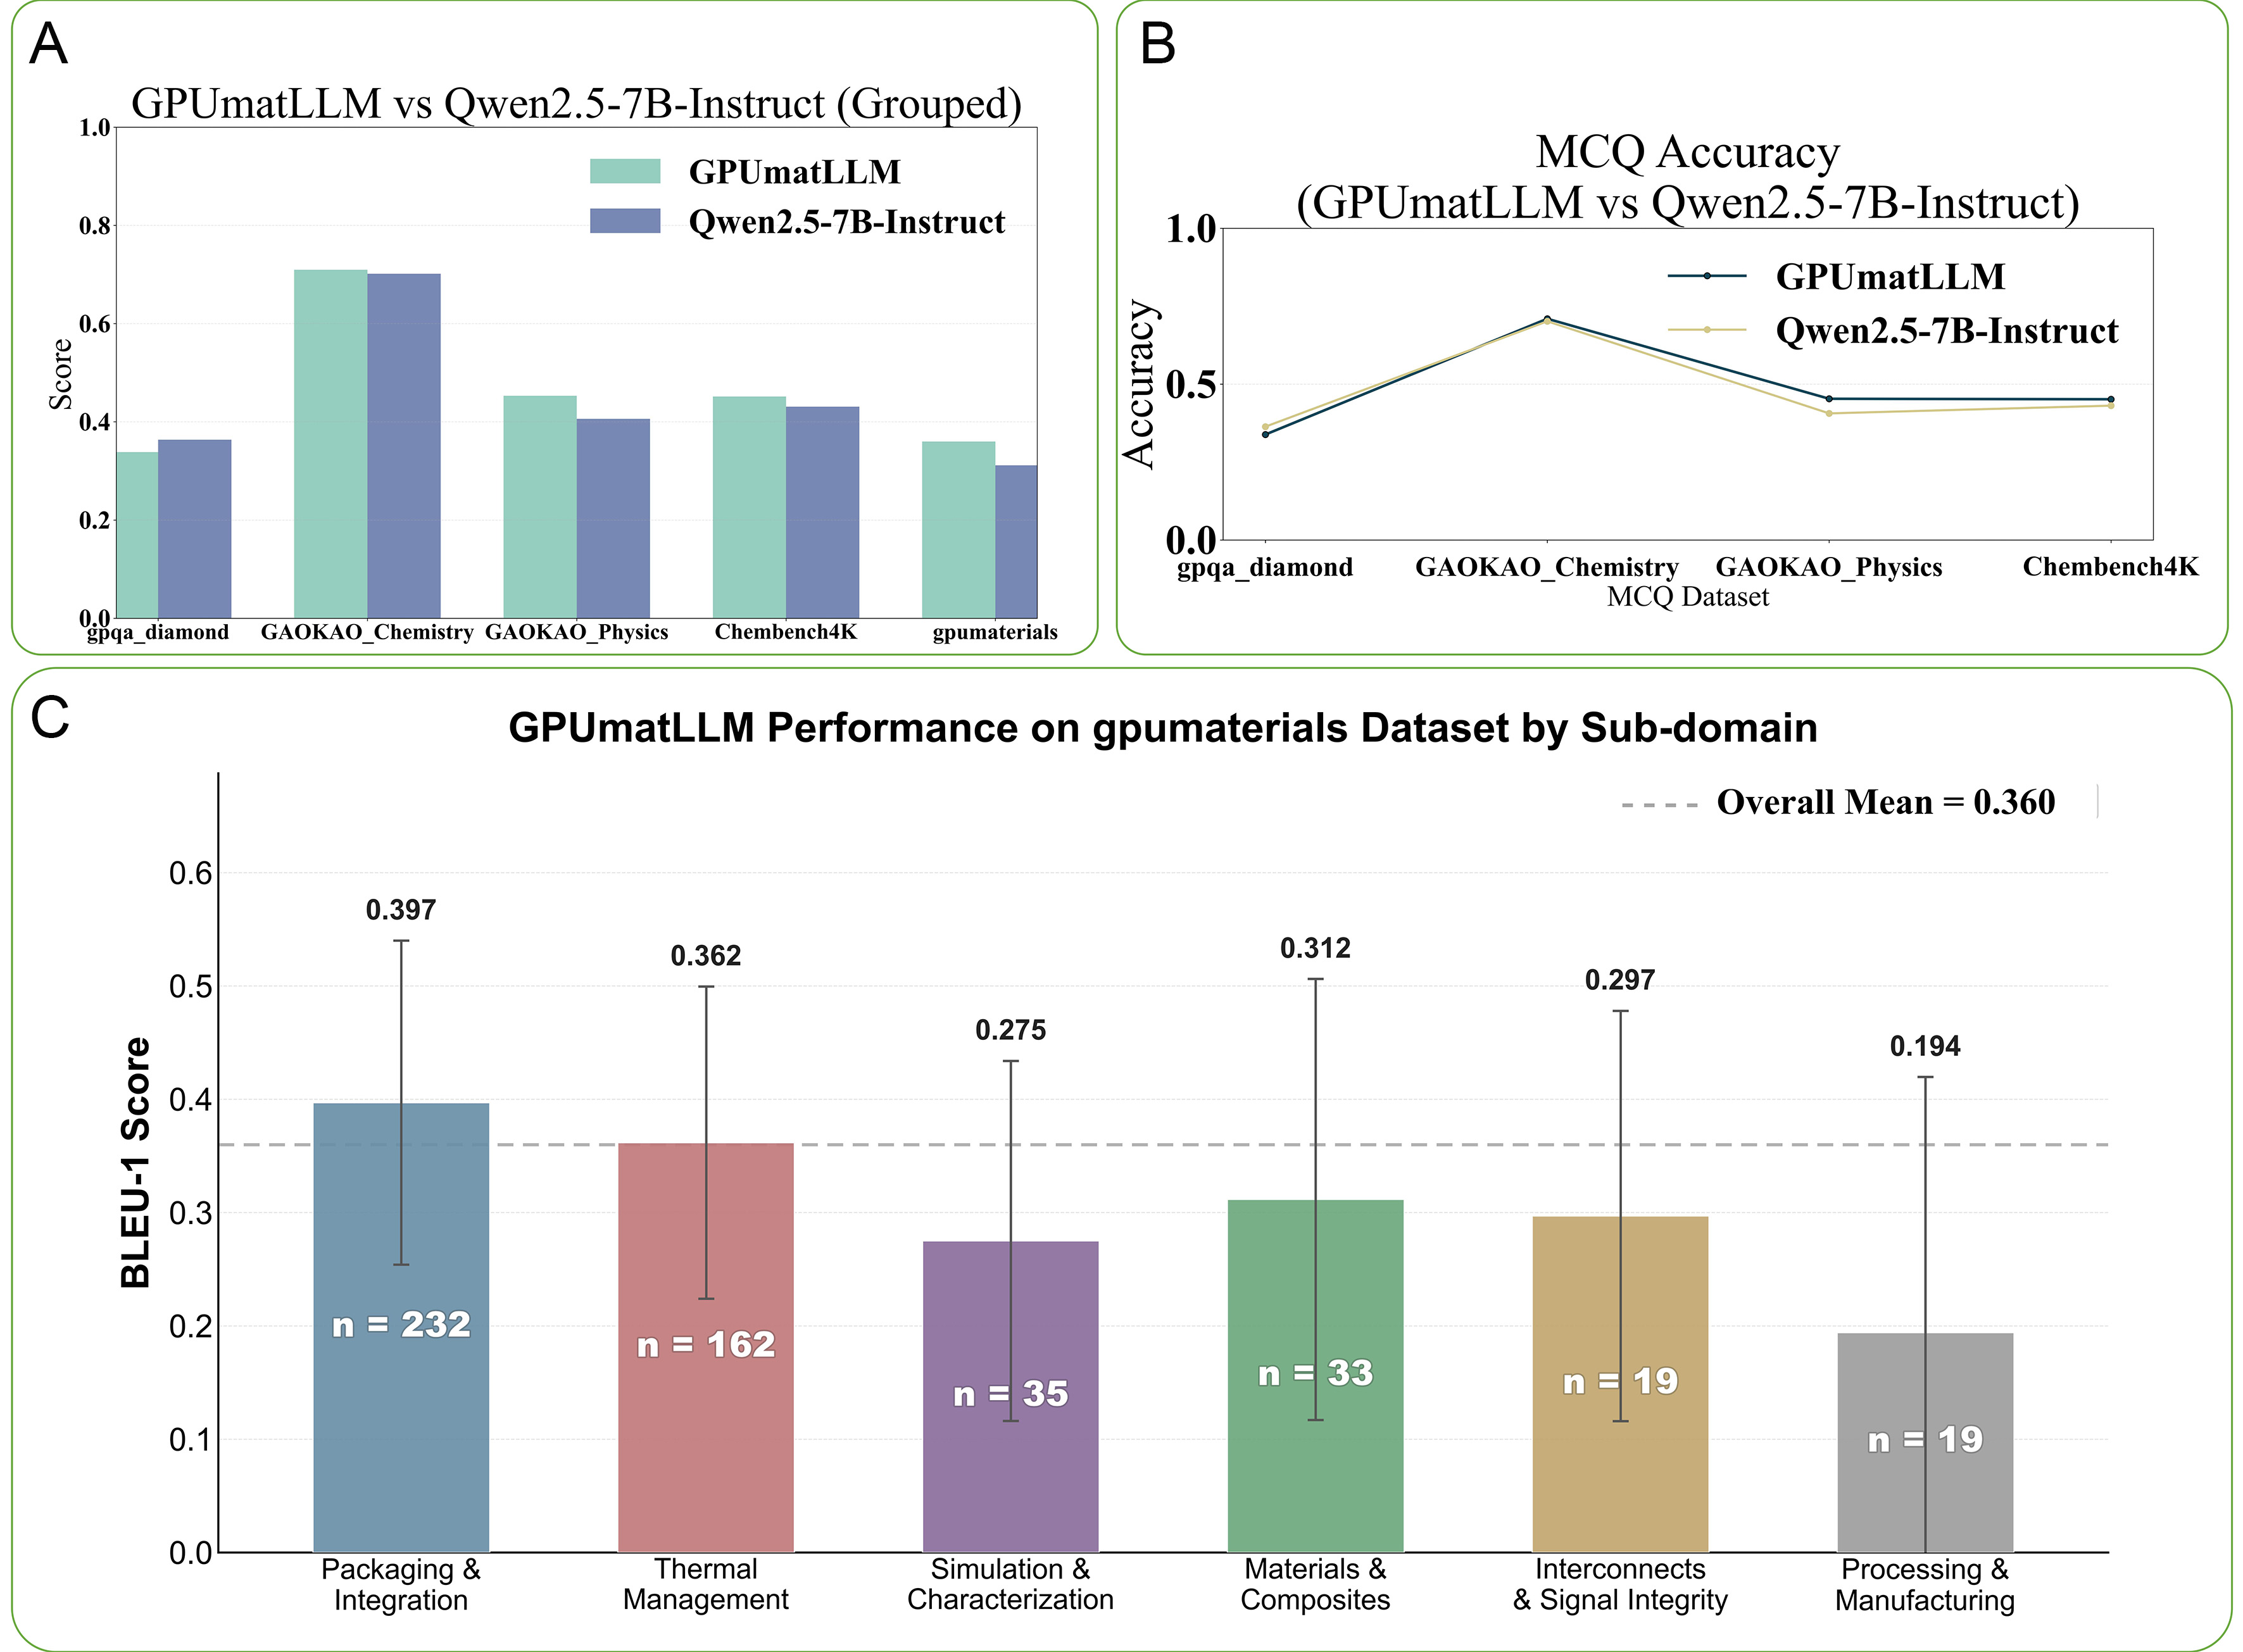
Figure 5. (A) Grouped bar chart comparing GPUmatLLM with its base model Qwen2.5-7B-Instruct across the five evaluation sets; accuracy is reported for the four MCQ benchmarks and BLEU-1 for gpumaterials; (B) Line chart comparing MCQ accuracy between GPUmatLLM (blue line) and Qwen2.5-7B-Instruct (yellow line) across four MCQ benchmarks: GPQA-Diamond, GAOKAO-Chemistry, GAOKAO-Physics, and ChemBench4K (x-axis, left to right). The y-axis denotes classification accuracy on a 0-1 scale; (C) GPUmatLLM performance on the gpumaterials benchmark by sub-domain; error bars denote one standard deviation, and n is the number of items per sub-domain. All panels were generated by the authors using Python with Matplotlib. MCQ: Multiple-choice question; BLEU-1: bilingual evaluation understudy, 1-gram; GPQA: graduate-level Google-proof Q&A.